

VLSplat lifts object-centric language semantics onto 3DGS with a scene graph
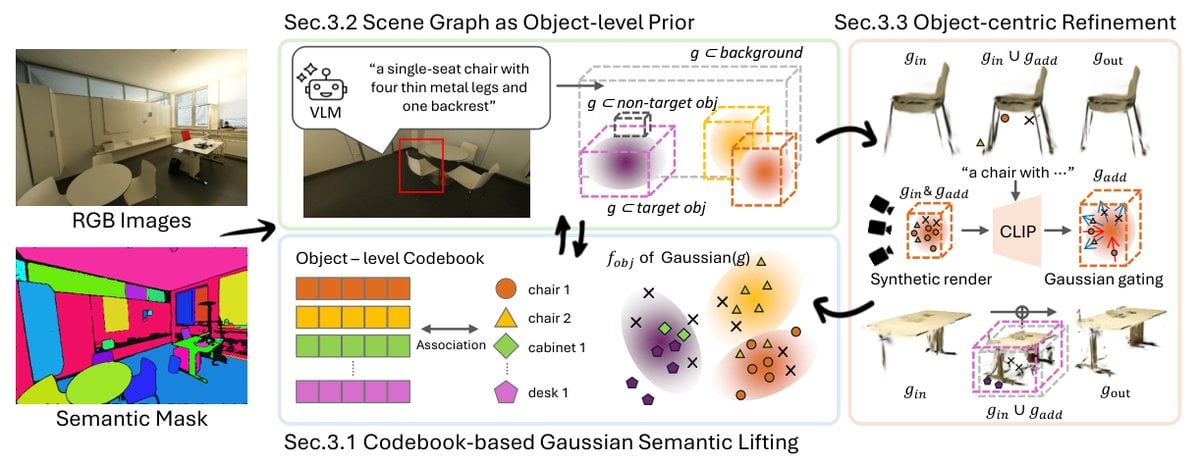
Yuntae Jeon, Younho Jeon, Sujin Jin, Sungho Jo and Seunghee Park present VLSplat, a vision-language-guided approach for object-centric semantic lifting in 3D Gaussian Splatting, accepted at NeurIPS 2026. They argue that existing 2D-to-3D semantic lifting relies primarily on 2D segmentation supervision and lacks object-level priors, so the learned representation is driven by local mask evidence rather than holistic object structure.
VLSplat augments mask-based lifting with object-level semantic priors from vision-language models and refines Gaussian representations using an object-group scene graph. Intra-group refinement suppresses semantic noise within object groups, and inter-group acquisition expands object support regions from neighboring groups. On indoor scene datasets, the authors report improved semantic consistency and structural completeness of object-level categories.