

VideoRNG generates relightable Gaussian assets with fur and feathers from a prompt or one image
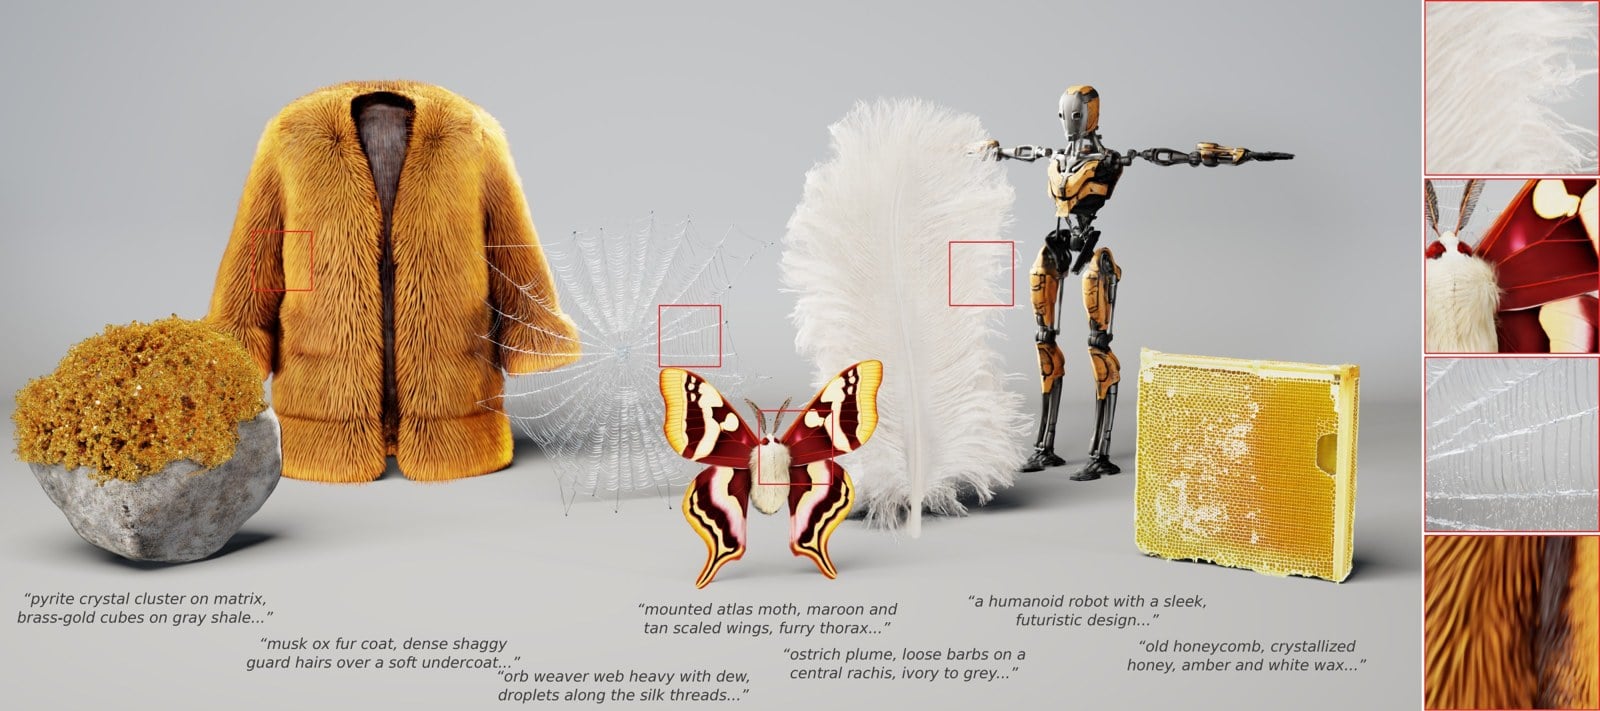
Bowen Xue, Saeed Hadadan, Fabrice Rousselle, Ravi Ramamoorthi, Zahra Montazeri and Miloš Hašan have posted VideoRNG: Relightable Neural Gaussians from Generative Video Models on arXiv. The two-stage method creates complete 3D assets from a text prompt or a single image without baking lighting into the result, which most Gaussian splat generators still do.
A video model fine-tuned from a pretrained video diffusion backbone first produces an RGBA turntable sequence under known pose, camera and lighting. A feed-forward reconstruction model then maps the video latents directly to millions of anisotropic Gaussians with learned neural appearance features, which a shared directional decoder and a stochastic Gaussian ray tracer turn into radiance under new viewpoints and illumination. The authors add depth-anchored appearance training to keep fine detail, and show assets such as fur, feathers and spider webs that can be rendered and relit interactively.