

Real2Sem2Real turns one human RGB video into thousands of robot demonstrations
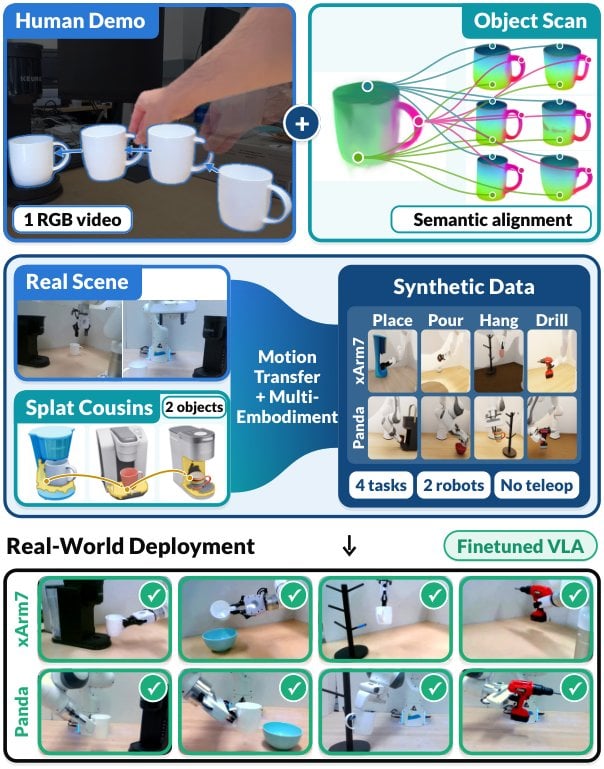
Matthew Strong, Ankush K. Dhawan and colleagues present Real2Sem2Real, a pipeline that turns one monocular RGB video of a human demonstration into thousands of robot demonstrations across semantic object instances of a category. Object SE(3) poses are tracked with DINOv3-distilled Gaussian splats, which the authors say outperform existing methods and FoundationPose with estimated metric depth, and digital cousins generated from one or a few photographs are aligned to the demonstrated objects, including functional regions such as a coffee machine’s tray.
Robot demonstrations are generated in IsaacSim or MuJoCo, and the system can produce over 2,000 episodes in about two hours. On two real robots and four tasks, policies trained on data from one human video per task match or exceed policies trained on teleoperation across diverse object instances.