

HumanSkill-4D queries animatable Gaussian avatars with language, without training
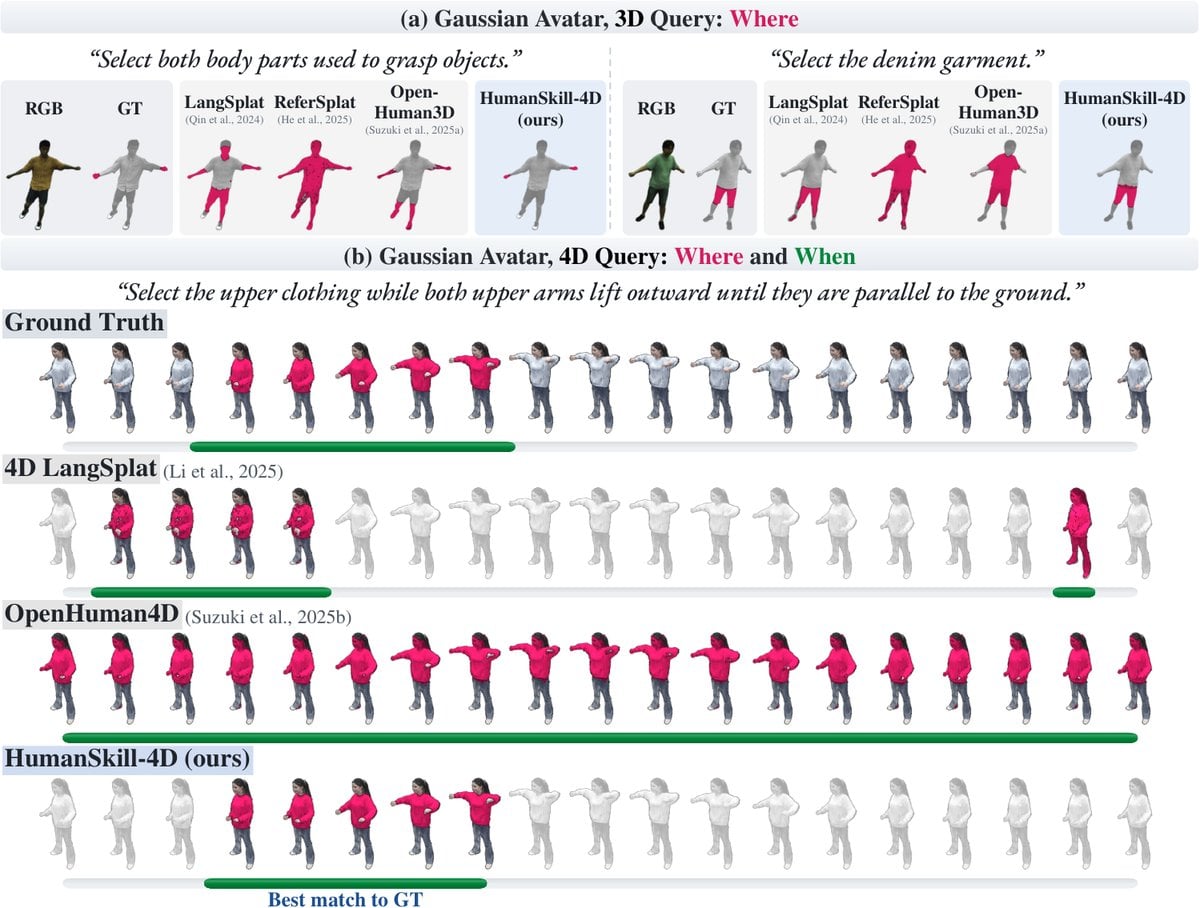
Junsu Kim, Naeun Kim, Dongyoon Han and Seungryul Baek present HumanSkill-4D, a training-free framework for avatar referring segmentation, which selects regions of animatable Gaussian avatars from language queries and can also specify a pose or motion to select matching intervals. A semantic memory links body-part and garment categories to persistent Gaussian regions, and a multimodal large language model selects categories and composes operators into programs that check conditions on stored joint trajectories.
The authors introduce three human-annotated benchmarks and report that HumanSkill-4D outperforms baselines in part segmentation and in 3D and 4D referring segmentation, with compact memories and only minutes of setup per avatar.