

NVIDIA Foundation4D predicts depth, objects, occupancy and Gaussians from driving video
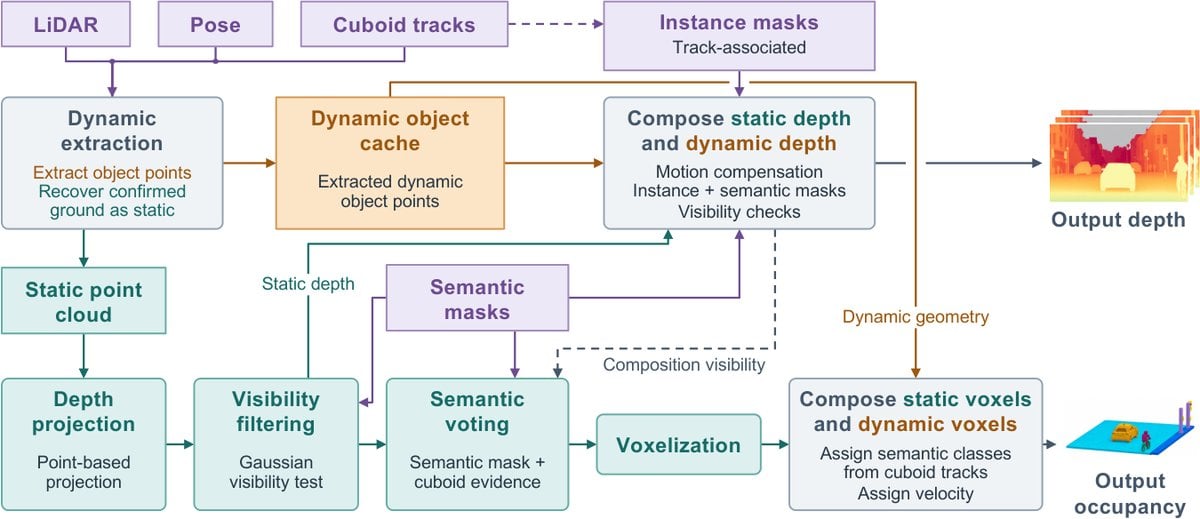
A 26-person NVIDIA team presents Foundation4D, a unified feed-forward model that, from multi-camera driving video, predicts camera poses and depth, 3D objects, semantic occupancy, and a set of Gaussians ready to render. A shared backbone uses factorized spatiotemporal attention; a Gaussian head places one Gaussian per pixel along each camera ray at the predicted depth, assigns it to static scenery or a tracked actor, and fills the sky from a learned background.
With benchmark-specific fine-tuning, Foundation4D reports the lowest depth AbsRel on Waymo and nuScenes, the highest detection mAP on nuScenes, and the highest occupancy mIoU on OpenOccupancy among the compared methods. Running on its own predicted poses and tracks, it scores 23.94 dB against 22.66 dB for the released Instant NuRec checkpoint across 99 internal clips. NVIDIA also releases the gated PAI-Foundation4D benchmark of 1,253 clips.